
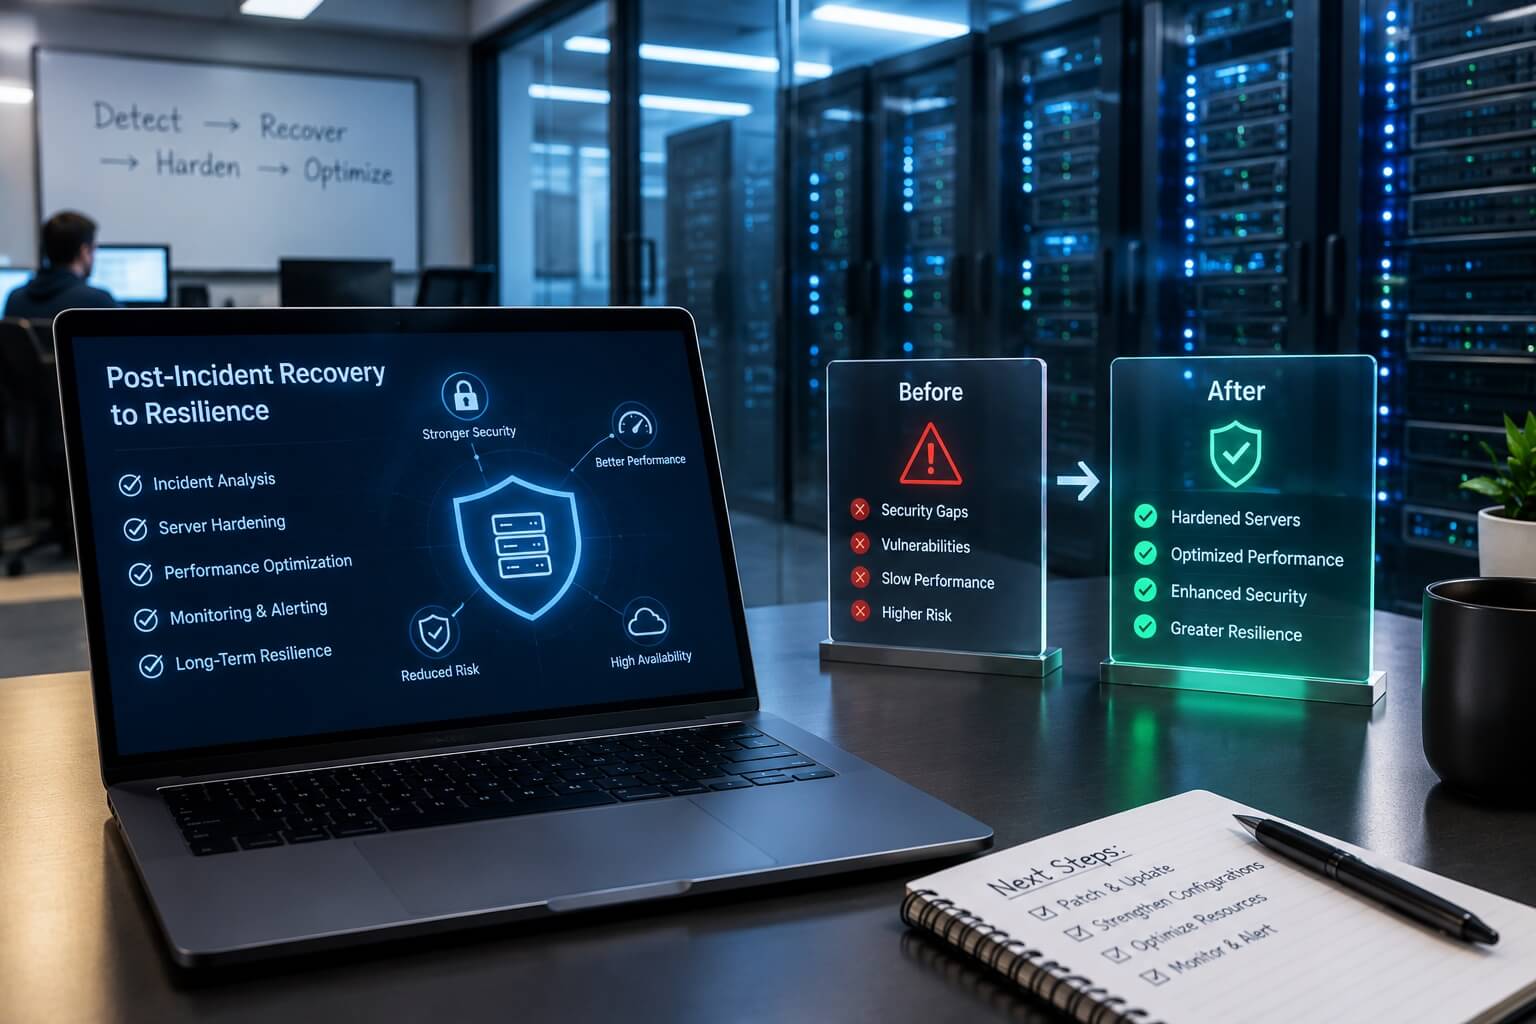
A security incident can leave a business focused on one question: How quickly can we get systems running again? Recovery is important, but returning a server to its previous state may leave weaknesses untouched. True resilience begins when organizations examine what happened, address vulnerabilities, and strengthen the environment for what comes next.
Why Post-Incident Server Hardening & Optimization Matters
Once operations resume, attention can easily shift back to everyday priorities. Yet the incident may have exposed outdated software, excessive permissions, weak configurations, or gaps in monitoring. This process helps turn those lessons into practical improvements.
Hardening reduces exposure by reviewing configurations, access controls, services, patches, authentication, and security policies. Optimization complements this process by examining performance, resource usage, stability, and configuration efficiency. Together, they create a server environment better prepared for changing demands.
Moving Beyond Simple Recovery
Recovery restores functionality; resilience asks why the disruption happened and what could reduce the possibility or impact of a similar event.
This distinction matters because a server that is operational is not automatically secure. Businesses need to investigate weaknesses before declaring recovery complete. Logs, system configurations, access records, and security findings can provide useful evidence for identifying areas that need attention.
Organizations can then prioritise improvements according to risk. This makes remediation more structured.
Building a Stronger Server Environment
Effective Post-Incident Server Hardening & Optimization should also consider the bigger infrastructure picture. A server does not operate in isolation; it interacts with applications, databases, networks, and other systems.
Improvements should be tested carefully. Unnecessary ports or services can be restricted, permissions can be reviewed, software can be updated, and monitoring can be strengthened. Performance testing can also ensure security measures do not create operational bottlenecks.
Documentation is valuable. Recording configuration changes, security decisions, and recovery procedures can make future maintenance more consistent and incident response more organised.
FAQs
Is server recovery enough after an incident?
Not always. Recovery restores availability, while hardening examines weaknesses that may have contributed to the incident. Both should form part of a broader security process.
When should hardening begin?
It should begin after immediate containment and recovery priorities are addressed, while investigation findings are still fresh. Post-Incident Server Hardening & Optimization can then guide structured remediation.
Can optimization improve security?
Yes. Removing unnecessary services, improving configurations, and managing resources effectively can support both performance and a more controlled server environment.
Turning Incidents Into Lessons
A security incident can disrupt operations, but it can also reveal where infrastructure needs greater attention. Post-Incident Server Hardening & Optimization helps businesses move beyond simply restoring yesterday’s environment. By combining investigation, hardening, optimization, monitoring, and documentation, organizations can build stronger foundations for tomorrow.
The objective is not to assume that every risk can disappear. It is to make the infrastructure more deliberate, controlled, observable, and prepared for the demands of a changing digital business landscape across the wider business.